Muse Glimmer 30B локально никто не тестил? Что там Мета нам придумала, интересно посмотреть.
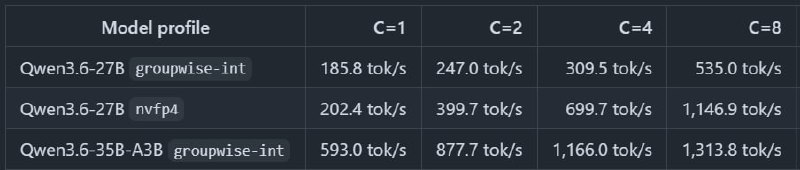
qwen 3.8 выложили в паблик. скоро 27b ожидают. Для владельцев 5090 возможно сделают аналогичное ninfer решение и можно ставить напостоянку локально, скорости просто отличные . Но пишут что сам qwen3.8 слабоват и как обычно все бенчмарки его в лидеры поставили. Да и 27b модели врядли будет достаточно для работы. Хотя скорости на старой qwen впечатляют
Это ты где прочитал? 3.6 9b они так и не сделали. И что-то мне подсказывает, что и тут не станут
До релиза остаётся чуть больше 2 часов
https://huggingface.co/Qwen/Qwen3.8-27B
Из интересного
- Context Length: 262,144 natively and extensible up to 1,000,000 tokens
- Qwen3.8 comes with official support for reasoning_effort, which can be used to adjust reasoning depth and control cost:
- xhigh (default): for complex tasks demanding thorough analysis
- medium: balancing accuracy and speed
- low: efficient reasoning optimizing for speed and cost
-
Vision-Language Understanding: Native support for image and video understanding, from STEM diagrams and documents to hour-scale videos.
-
3.6 27b has 92% of the score of it’s Max version. In theory, we could get a 3.8 27b with 53 score(https://artificialanalysis.ai/evaluations/artificial-analysis-intelligence-index), parring with GLM 5.2 and deepseek v4. I would buy a gpu at that point